Every industry has its own version of the same problem: the signal is scattered across RSS feeds, official accounts, JSON APIs, and social posts, and someone has to read all of it before breakfast to decide what actually matters. The repository we are touring today started life as one person’s answer to that problem for the AI field, and then did something rarer — it published the entire machinery, prompts and thresholds included, so anyone can rebuild the same kind of site for law, HR, finance, or any other field.
AIHOT is the complete framework behind aihot.news, an AI news site that collects material from a batch of sources every day, lets a language model pre-filter it and then score it twice and independently, writes Chinese titles and summaries, clusters reports of the same story into one event, ranks events by how many independent sources are talking about them, and ships a daily briefing at 08:00. The author describes it as a snapshot of the code that runs the live site, not a polished generic framework — which is precisely what makes it interesting to read. Every prompt used at every step lives in the repository, alongside the selection thresholds that decide what makes the cut.
The source is worth a tour for three reasons. First, it is an end-to-end product, not a demo: three processes, a job queue, a database, an admin backend, and a public API all ship together. Second, the “editorial brain” is fully externalized — the industry knowledge sits in a folder of Markdown prompts and a thresholds file, so the code and the judgment are cleanly separated. Third, the design rules that keep a site like this alive in production (pages never call models, paid API calls leave receipts, budgets trip circuit breakers) are implemented in small, readable modules rather than hidden inside a framework.

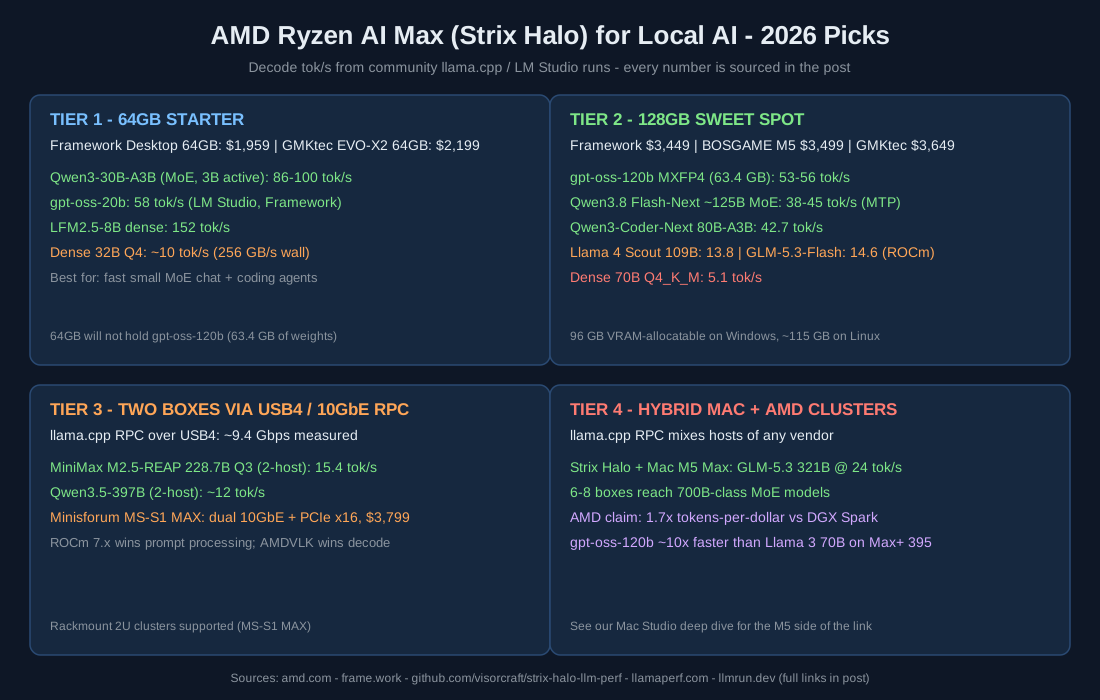
High-level architecture overview of the KKKKhazix/AIHOT repository, tracing material from collection through judging, event clustering, and serving.
Reading the overview from left to right: a worker process drives the collection scheduler, which pulls from six kinds of source readers and stores deduplicated material; the material store enqueues each item into the judge-and-write pipeline, which loads its prompts from the industry pack and calls models through a metered provider layer; selected items flow onward into event grouping, where related reports are merged and heat is computed per event; and everything readers see is served from a single public read layer that backs the web pages, the RSS feeds, the public API, and the daily, weekly, and monthly briefings.
Why You Need This
Building a news aggregation site looks easy until you try it. Fetching feeds is a weekend project; deciding what deserves a reader’s attention is not. A naive aggregator either floods you with everything or hides the important story behind a bad keyword filter. AIHOT’s answer is a layered funnel: a cheap pre-filter first asks whether an item even belongs to the domain, then the surviving items are scored against the industry’s written taste, and the score threshold is tiered by source — an official first-party announcement does not need to shout as loudly as a random repost to be selected.
The second problem is duplication. One real event produces an official blog post, ten media write-ups, and a day of arguing on X, and a reader should see it once. Treating every article as independent inflates the news list with echoes. AIHOT clusters reports of the same occurrence into a single event with its follow-ups attached, and computes heat per event rather than per article, so the front page reflects how many independent participants are talking, not how many copies exist.
The third problem is operational cost. Language models, embedding APIs, and social data providers all charge per call, and a crawler that retries on failure can silently pay twice for the same result. The framework records a receipt before every paid call, stores the result first, and reuses it across process restarts and job retries — a small piece of engineering discipline that most hobby projects learn about the expensive way. If you have ever wanted a curated industry news site, or even just a defensible morning briefing for your team, this repository hands you the full pipeline with the policy knobs exposed.
How It Works
The framework runs as three processes — a Fastify API, a pg-boss worker, and a React Router server-rendered web app — backed by PostgreSQL, with all business logic shared in a backend package.

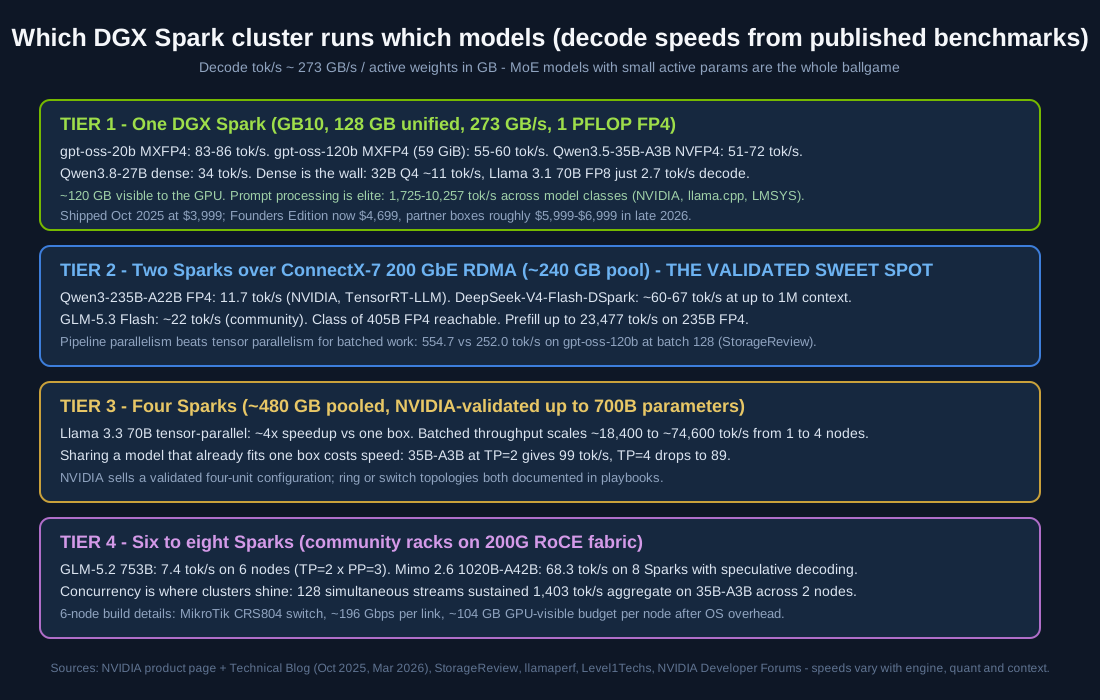
Detailed architecture of the KKKKhazix/AIHOT repository, from source readers and the material store through the editorial pipeline, event grouping, publication, and operations.
Understanding the Architecture
Collection is cursor-based and failure-aware. The worker’s schedules in apps/worker/src/schedules.ts trigger collection runs implemented in packages/backend/src/sources/collect.ts. Each run fetches a listing, filters noise with per-source keep and drop markers, and stores candidates with a hard cap of 60 items per run. A failed fetch never advances the success cursor, so a source that breaks reflects its health honestly instead of pretending the world went quiet.
Six kinds of sources share one funnel. Readers for RSS, web page lists, JSON APIs, X searches, and WeChat public accounts live in packages/backend/src/sources/ (rss.ts, web-list.ts, x.ts, mp.ts), and anything else can be pushed in through the external ingest endpoint in apps/api/src/routes/ingest.ts. Material lands in packages/backend/src/content/materials.ts, which assigns identities and deduplicates before anything expensive happens; items with only a title get their article page fetched by packages/backend/src/content/extract.ts before judging.
Judging is a four-step pipeline with every prompt in the open. packages/backend/src/editorial/analyze.ts runs prefilter, two independent scores, writing, and structure extraction. The two scores are summed and compared against the threshold for the source’s tier from industry/selection.ts — selected when the sum clears twice the threshold. Prompts come from industry/prompts/ (selection-score.md, prefilter.md, and the writing rules such as answer-first summaries and anti-hallucination guards), and packages/backend/src/editorial/models.ts routes each step to its own model, so the cheap steps and the expensive reasoning never share a configuration.
Event grouping separates recall from identity. packages/backend/src/events/group.ts recalls candidate facts from the last 14 days using title-and-summary embeddings from packages/backend/src/providers/embeddings.ts with a cosine floor, then makes a three-way relation judgement — same occurrence, follow-up development, or distinct story — through packages/backend/src/events/relate.ts. Merges that similarity alone cannot vouch for are confirmed by a second model vendor before they are written. Manual corrections are never overwritten, and grouping runs serially so a regroup in discovery order sees what live grouping would have seen.
Heat is computed over events, not articles. packages/backend/src/events/hot.ts counts independent participants per story over a 48-hour window with a 24-hour half-life decay, counting each participant once per window no matter how many times it was collected. Evidence is placed by the source’s own publication time rather than the collection time, and sources that have fallen behind are marked so the ranking can show a comparable view. The result is a hot list where rising events are flagged against their position six hours earlier.
One read layer feeds every outlet. Pages, RSS, the public API, MCP, sitemaps, and share images all read through packages/backend/src/publication/, so the website in apps/web and the agent-facing outputs in apps/api never disagree. Briefings are composed by packages/backend/src/reports/compose.ts — daily at 08:00, weekly on Mondays, monthly on the first — and the operations modules handle alerts, backups, retention, and a Feishu notification channel.
End to end: a scheduler fires a collection run, new material is stored and deduplicated, the editorial pipeline filters and double-scores it, selected items get Chinese titles and summaries written, grouping merges reports of the same occurrence into events with digests, heat ranks the events, and the public read layer serves the result to readers, RSS subscribers, and agents alike.
Advantages
- Policy lives outside the code. Selection taste, writing rules, categories, topics, and thresholds are all in the industry/ folder, so changing what your site considers important does not mean touching TypeScript.
- Two independent scores beat one. Requiring agreement between two scoring calls before selection reduces both false positives and the variance of a single model’s mood.
- Heat that resists echo inflation. Counting each independent source once per window and ranking events rather than articles keeps the hot list honest under syndication storms.
- Receipts for every paid call. The provider layer records each billable request and reuses its result across retries and restarts, which turns “the crawler went crazy” from a billing incident into a non-event.
- Budget circuit breakers built in. Every paid service has per-minute, hourly, and daily caps that pause spending when exceeded, configurable from the admin backend.
- Agent-ready by design. The same content ships as RSS variants, a documented public API, an MCP endpoint, and llms.txt, so human readers and automated consumers see one truth.
Benefits
- A production blueprint, not a toy. The three-process split, the job queue, migrations, tests that run without external services, and the operational modules show how to run an LLM-powered site that keeps its costs and failures visible.
- Fast path to your own vertical. Hand the repository to a coding agent together with AGENTS.md and docs/customize.md, describe your field, and the customization is concentrated in one folder you can review line by line.
- Calibration you can actually do. The SelectBench flow and scripts/eval-selection.ts let you score the pipeline against your own labeled samples and tune the written thresholds until selection matches your judgment.
- Honest defaults. Content published more than 48 hours before discovery is archived rather than pushed, old events keep their addresses when regrouped, and manual editorial fixes survive automatic reprocessing.
- Readable at every layer. Each module — collect.ts, analyze.ts, group.ts, hot.ts — is small and documented in its header comments, making the system a study aid as much as a tool.
- Switchable extras. The model leaderboard and the Codex reset monitor that power the live site’s AI-specific pages are one flag away in industry/features.ts if your industry does not need them.
Usage
The project targets Node.js 24 and runs on Docker Compose with PostgreSQL; you need Docker and an OpenAI-compatible model API key (the README names DeepSeek, Qwen, and Zhipu as options):
git clone https://github.com/KKKKhazix/AIHOT.git myhot
cd myhot
node scripts/init-env.ts --llm-key <your-model-api-key>
docker compose up -d --build
Open http://localhost:3000 for the site; the admin backend lives at /admin with the password in the ADMIN_PASSWORD entry of .env. First-run migrations and seed data are applied by the setup service before the API and worker start, and imported material begins appearing within a couple of minutes.
For a public deployment with a domain and automatic HTTPS, the compose file ships a Caddy profile:
docker compose --profile https up -d --build
To turn the site into your own industry edition, the README’s recommended route is to let a coding agent do the typing while you supply the domain knowledge:
Please read AGENTS.md and docs/customize.md and turn this site into a
news site for the legal industry. What I care about is: ... (which
sources to watch, what counts as important, and what does not — the
more specific, the better).
The files to review afterwards are industry/site.ts for naming and copy, industry/sources.json for the seed sources, industry/prompts/ for the selection and writing standards, and industry/selection.ts for the thresholds. To check how well selection matches your taste, label a couple hundred of your own items and run scripts/eval-selection.ts against them.
Conclusion
AIHOT is a rare kind of open-source release: the working code behind a live, opinionated product, stripped of its secrets but not of its engineering. Its pipeline — collect, deduplicate, pre-filter, double-score, write, cluster, rank, publish — is a complete answer to the question of how an LLM should curate news without hallucinating importance into existence, and its rules (one read layer, no models on page loads, receipts on paid calls) generalize far beyond news sites. If your field deserves its own morning briefing, the embers are already here; the README’s parting line makes the intent clear: the rest of the road is handed to you.
Links:
- GitHub repository: https://github.com/KKKKhazix/AIHOT
- Live site: https://aihot.news/
- Architecture documentation: https://github.com/KKKKhazix/AIHOT/blob/main/docs/architecture.md
- Customization guide: https://github.com/KKKKhazix/AIHOT/blob/main/docs/customize.md

Enjoyed this post? Never miss out on future posts by following us